Service
This page describes the service architecture and its specifications.
The service is a FastAPI application that is deployed on a Kubernetes cluster. It is a REST API that can be used to process data.
Architecture
To see the general architecture of the project, see the global UML Diagram.
This sequence diagram illustrates how a client executes a service through the Core AI Engine. The Core AI Engine owns the connection to its S3-compatible object storage. The service transfers task files through the Core AI Engine's HTTP storage endpoint and does not receive storage credentials.
sequenceDiagram
    participant C as c - Client
    participant E as e - Core AI Engine
    participant S as s - Service
    participant O as o - Object storage
    C->>+E: POST(/service-slug, data)
    E->>+O: Store input files
    O-->>-E: Return file keys
    E->>E: Create ServiceTask(storage_url, task, callback_url)
    E->>+S: POST(/compute, service_task)
    S-->>-E: return(200, Task added to the queue)
    E-->>-C: return(200, task)
    S->>+E: GET(service_task.storage_url/{key})
    E->>+O: Read input file
    O-->>-E: Return file
    E-->>-S: return(200, file)
    S->>S: result = process(data)
    S->>+E: POST(service_task.storage_url, result file)
    E->>+O: Store result file
    O-->>-E: Return file key
    E-->>-S: return(200, key)
    S->>S: task_update = jsonable_encoder(TaskUpdate({status: finished, task.data_out: data_out}))
    S->>+E: PATCH(service_task.callback_url, task_update)
    E-->>-S: return(200, OK)
    C->>+E: GET(/storage/{key})
    E->>+O: Read result file
    O-->>-E: Return file
E-->>-C: return(200, file)Specifications
Inside the project, the services are implemented using Python. But the service is a REST API, so it can be implemented in any language.
Access levels
Each service registered in the Core AI Engine has an access_level. New and existing services default to public.
| Access level | Anonymous visitor | User | Admin |
|---|---|---|---|
public | Yes | Yes | Yes |
user | No | Yes | Yes |
admin | No | No | Yes |
disabled | No | No | No |
The access level controls both discovery and execution:
GET /servicesreturns only services available to the caller's role.- Service detail, wake-up and code-snippet endpoints return
404 Not Foundfor an inaccessible service. This avoids revealing a restricted service through the regular catalog API. - A generated service execution endpoint checks the current database value on every request and returns
403 Forbiddenwhen the caller lacks access. GET /admin/servicesreturns all services, including disabled ones. An administrator changes access withPATCH /admin/services/{service_id}/access.
Public catalog routes accept an optional bearer token. Without one, the caller is treated as anonymous. See Authentication and authorization for login and role details.
Note
Access level is separate from operational status. A service can be public but unavailable, or running but disabled for regular discovery and use.
Endpoints
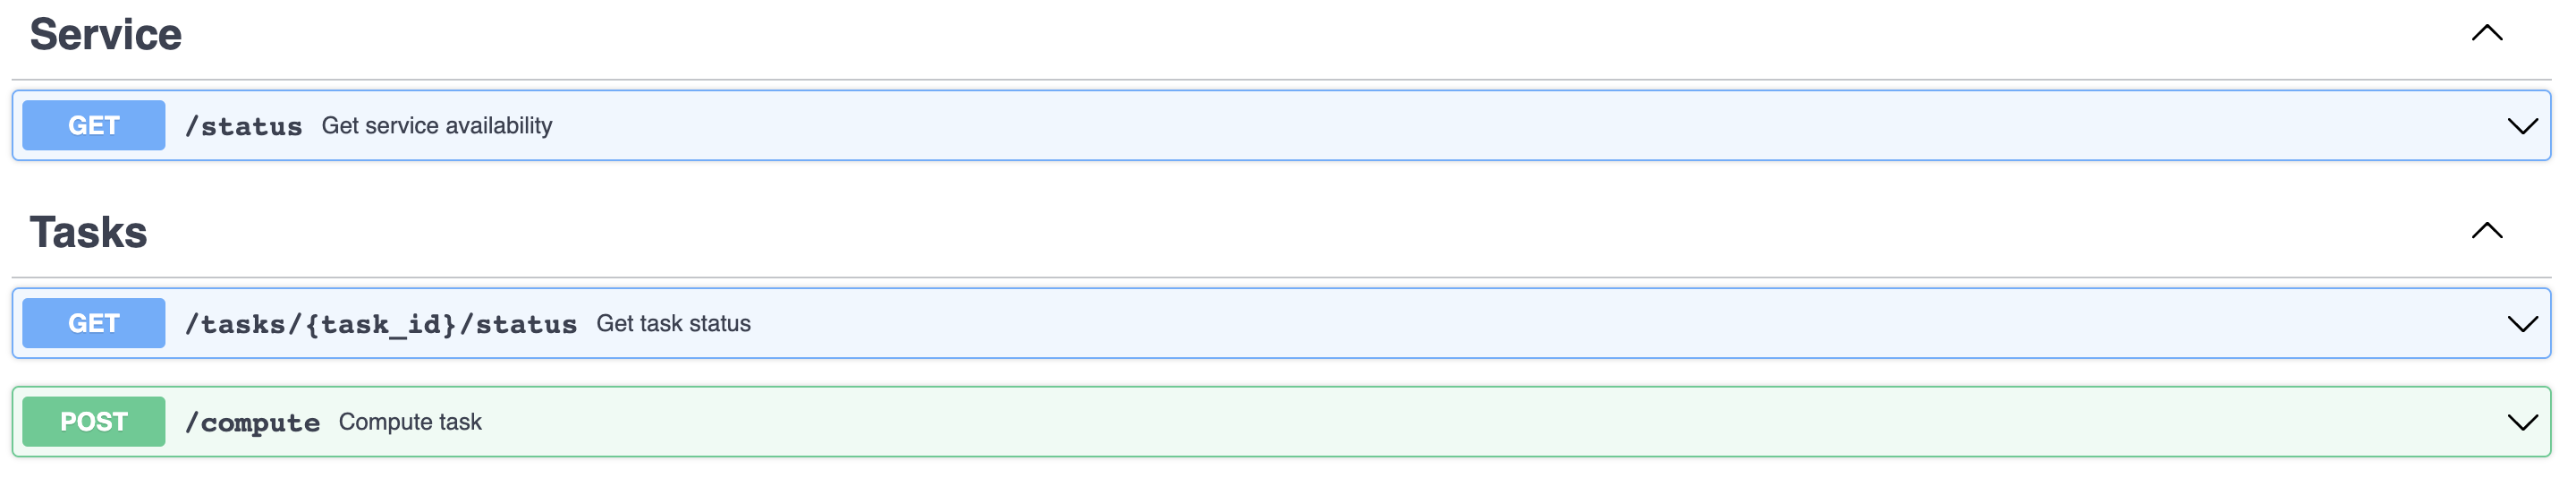
To match the specifications, the service must implement the following endpoints:
- GET
/status: returns the service availability. (Returns a string) - GET
/tasks/{task_id}/status: returns the status of a task. (Returns a string) - POST
/compute: computes the given task and returns the result. (Returns a string)
Models
The different models used in the pipeline are described below.
Task Input
The POST /compute endpoint must be able to receive a JSON body that matches the following model:
The data_in and data_out fields are lists of storage object keys. The status field is a string that can be one of the following values:
The storage_url is the Core AI Engine storage endpoint. The service downloads each input with GET {storage_url}/{key} and uploads each result as multipart form data with POST {storage_url}. The upload response contains the result object's key. The callback_url is the URL where the service sends its task status and output keys.
The Core AI Engine keeps the S3-compatible storage configuration and credentials. They are not part of ServiceTask and are not sent to services.
A JSON representation would look like this:
Task Output
Once the task is computed, the service must PATCH the task on /tasks/{task_id} with the following model:
The data_out field is a list of storage object keys. The status field is a string that can be one of the following values:
A JSON representation would look like this:
Register to the Core AI Engine
To register the service to the Core AI Engine, the service must send a POST request to the Core AI Engine /services endpoint with the following model:
The data_in_fields and data_out_fields fields are lists of FieldDescription models. A FieldDescription model is defined as follows:
The url field is the url of the service.
A JSON representation would look like this:
After the service is registered, it will be available on the Core AI Engine's /service-slug endpoint.
Environment variables
All environment variables are described in the .env file at the root of the repository.
The values can be changed for local development. For example, to have multiple services running on the same machine, The SERVICE_PORT variable can be changed to a different port number.
Run the tests with Python
Info
You might need to initialize a virtual environment before running the tests.
Check the Start the service locally > Start the service locally with plain Python to initialize and activate a virtual environment.
For each module a test file is available to check the correct behavior of the code. The tests are run using the pytest library with code coverage check. To run the tests, use the following command inside the service folder:
Start the service locally
Tip
If you are not familiar with the Core AI Engine and its services, we recommend to follow the Getting started guide first.
The Core AI Engine is highly recommended to test the service locally.
You have several options to start the service locally:
- Start the service locally with Docker Compose (recommended)
- Start the service locally with plain Python
- Start the service locally with minikube and official Docker images
- Start the service locally with minikube and local Docker images
In the service directory, start the service with the following commands:
Access the service documentation at http://localhost:9090/docs.
Access the Core AI Engine on http://localhost:3000 or http://localhost:8080/docs to validate the service has been successfully registered to the Core AI Engine.
In the service directory, start the service with the following commands:
Start the application.
Access the service documentation on http://localhost:9090/docs.
Access the Core AI Engine on http://localhost:3000 or http://localhost:8080/docs to validate the service has been successfully registered to the Core AI Engine.
Start the service with the following commands. This will start the service with the official Docker images that are hosted on GitHub.
In the service directory, start the service with the following commands:
Create a tunnel to access the Kubernetes cluster from the local machine. The terminal in which the tunnel is created must stay open:
Access the service documentation on http://localhost:9090/docs.
Access the Core AI Engine on http://localhost:3000 or http://localhost:8080/docs to validate the service has been successfully registered to the Core AI Engine.
Warning
The service StatefulSet (stateful.yml file) must be deleted and recreated every time a new Docker image is created.
Start the service with the following commands. This will start the service with the a local Docker image for the service.
In the service directory, build the Docker image with the following commands.
In the service directory, start the service with the following commands.
Create a tunnel to access the Kubernetes cluster from the local machine. The terminal in which the tunnel is created must stay open.
Access the service documentation on http://localhost:9090/docs.
Access the Core AI Engine on http://localhost:3000 or http://localhost:8080/docs to validate the service has been successfully registered to the Core AI Engine.